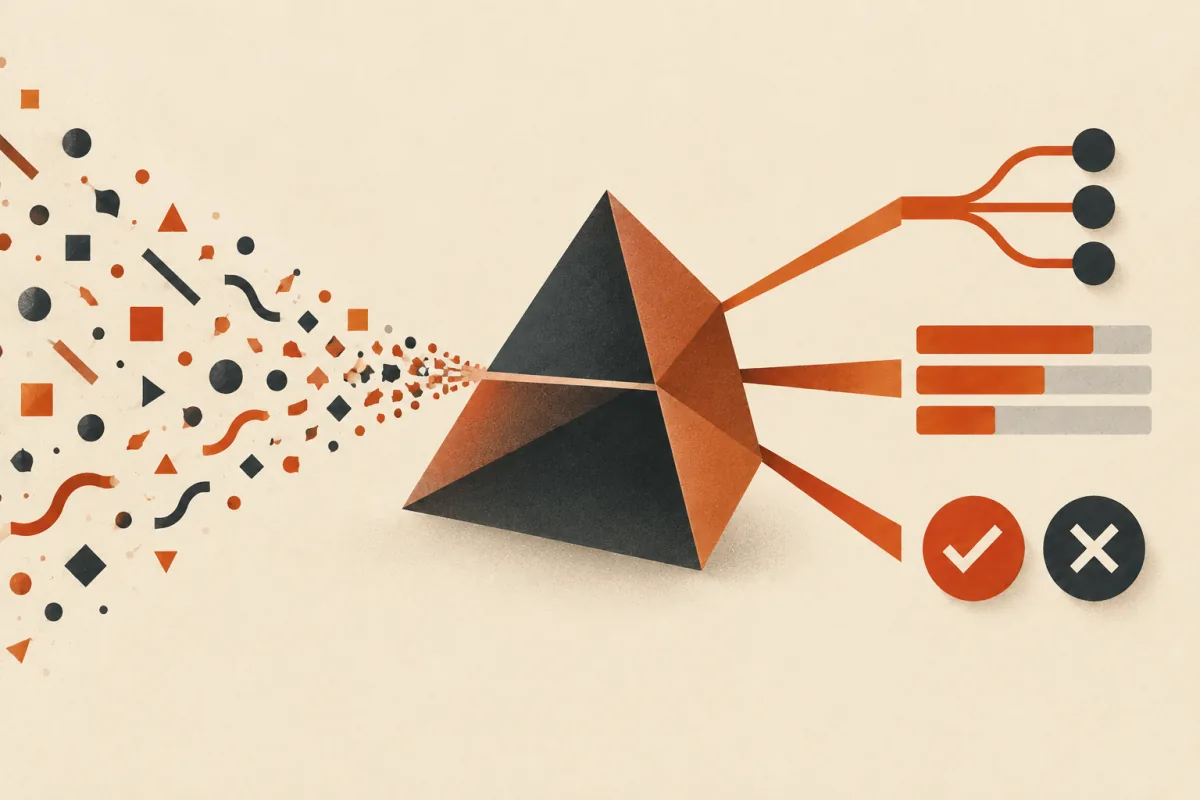
If you ask a regular language model to distribute a letter into departments, it will first write the answer in words, and your program will then try to extract the desired meaning from it. Jev offers a different interface: you pre-specify the options, pass in the context, and get a typed solution with probabilities.
For example: “Where should I send the request - support, billing or sales?” The output is not a paragraph of explanation, but one of these options and assessments associated with the answer. The application itself decides what to do next: assign a queue, ask a person to check the case, or do not change anything.
This is not a new chatbot or a universal replacement for ChatGPT. Jev is the first System One model from TypeSafe AI, publicly unveiled on September 15, 2026. Its idea is to perform limited semantic tasks within programs: classify, select, evaluate and verify. Below we will look at what is behind this, how to try the model and how not to confuse the “correct type of answer” with the “correct answer”.
On your fingers: a smart if that you can ask a question to
Regular if is good when the condition can be accurately described: if the order amount is more than 10,000 rubles, send a request to the manager. But the code itself does not know that the phrase “I was charged twice” refers to payment, and “I can’t log in after changing my phone” refers to access.
The chat model can understand the text, but her usual result is a free line. In order for the program to use the response, it must be limited by the schema, checked, and then separately handle errors. Jev responds natively in predefined types. A simplified flow looks like this:
текст обращения + вопрос + допустимые ответы
                       ↓
                   ответ Jev
                       ↓
     правила и действия вашего приложения
You set the boundaries of the question and acceptable results. The model interprets the context, but does not send an email, change the order, or call the tool itself. This makes it look like a semantic block inside the program - like if, only for cases where the rule depends on understanding the text.
The name System One refers to “fast thinking” from the book by Daniel Kahneman. It is important not to carry the metaphor too far: System One is a TypeSafe term for its class of models and interface, and not a scientific guarantee of error-free intuition.
Three basic types of response
There are three types of questions in official Jev integrations. The names of individual fields may differ in different SDKs, so when changing a library, check its documentation.
| Type | What returns | Example |
|---|---|---|
| Choice | One option from the list and probability distribution over options | Where to send your appeal: billing, technical, other? |
| Score | Rating on a given scale with described levels | How urgent is the response on a scale from “usually” to “critical”? |
| Noul / Boolean | Probability that a particular statement is true | Does the person ask for a refund? |
Choice is suitable for choosing one direction, and not for inventing a new category. Therefore, the list of options must be thought out in advance. If your process frequently encounters ambiguous cases, consider “insufficient data” or “other topic.” Otherwise, the model will be forced to choose between bad answers.
Score is only useful in conjunction with a clear rubric. “Rate importance from 1 to 10” leaves too much room for variation. It's better to explain what each end of the scale means: for example, "generally - work available, there is a workaround" and "critical - users cannot complete payment, there is no workaround."
Noul is the TypeSafe name for the answer about the probability of a "yes" statement. It is not synonymous with confidence in any sense. The probability of approval, the chosen option, and the separate confidence metric are different signals. Don't substitute one for the other, especially when porting code between SDKs.
Where the model can be useful
Distribution of incoming requests. Select a support queue, define the topic of the request, or separate the payment question from the technical problem. If the decision only affects internal routing, a human can usually correct the error.
Initial assessment of urgency. Assign the message to pre-described priority levels to help the operator clear the queue. This is a hint for the process, and not a reason to automatically refuse the client.
Checking the result of another AI. Evaluate whether the generated text answers the question, meets a given criterion, or contains a specific objectionable statement. Free text and explanation are still best left to a generative model or human.
Selecting the next step in the agent. Based on the current state, decide whether to request the missing information, search for a document, or transfer the case to the operator. The tool itself runs the application code, and the access rights check the code.
Selection and classification of materials. Arrange documents according to predefined topics, evaluate whether the text meets the criteria, or select the appropriate item from the available list. For images, audio and video, you will first need a separate step: extract text, captions or transcript.
A good candidate for Jev is an iterative solution where the options can be described before launch and the correct answer can be tested with examples. Whether you need a new idea, a detailed explanation, or a ready-made answer to a person, that's a challenge for a generative model. If the condition is already clearly written in code, call the code directly: the model will add cost and another source of error.
How is this different from the chat model's JSON response
A modern language model can also be asked to return an object like { "team": "billing" }, set Structured Outputs and validate fields. This is a useful approach, but JSON alone does not indicate that the correct department has been selected. It guarantees the form of the result - subject to compliance with the contract - but the quality of the solution must be measured separately.
Jev is distinguished by its specialization and interface: the question and answer system is designed for standardized assessments, and probabilities and confidence are included in the work model. TypeSafe states that due to restricted types, the response cannot invent a missing field or category outside the declared list. This is a real advantage at the data form level. But Jev can still misread the context and choose a valid but incorrect option.
In its own announcement, TypeSafe provides price and speed figures and the results of its comparisons. The company also reveals the limitations of the tests: one demo query was simplistic, while another controversial example produced an ambiguous answer; workflow assessments use responses from large external models as a guide, and individual scenarios are prepared by team members. This is useful manufacturer data, but not independent proof that Jev will be more accurate or faster on your set of tasks.
Integration examples Vercel show a practical separation: Jev selects a typed response, and the application associates it with a queue or next step. LangChain material about LangSmith Evals describes his own experiment on one agent task. This is an interesting pilot, but its numbers also cannot be automatically transferred to your product.
How to get access now
As of September 23, 2026 The official TypeSafe announcement on September 15 talks about early access and gradually inviting people from the waitlist. This does not confirm that direct TypeSafe API keys are already being issued to everyone without a queue. You can start checking direct access from TypeSafe consoles i official documentation; Check the availability of the key and registration there, it may change.
There are other routes:
- Vercel AI Gateway. Integration uses the model
typesafe-ai/jev. Vercel announcedthat Jev is free through the AI Gateway until September 25, 2026. This is a temporary promotion at the time of publication: before the test, check the current conditions and tariffs in your account. - Cloudflare Workers AI. The official Vercel manual shows the ID
typesafe/jev; To launch, you need a suitable Cloudflare account and credentials. - Python / JavaScript SDK TypeSafe. Convenient if the key has already been obtained: the official Python client is installed as
typesafe-sdk, JavaScript/TypeScript —@typesafe-ai/sdk. - Existing stack. For LangChain there is
TypeSafeClassifier; There are separate integration methods for applications based on the AI SDK, TanStack AI and the eve agent framework.
The presence of a model in the integration catalog does not automatically mean that the call is free or that you already have permission for direct access. In this article, we did not create an account or launch a request on behalf of the reader; This is a documentation review, not a report on our own testing of the model.
Minimal example in Python
Below is a short example from the official Python SDK. It accepts a test text and asks you to select a queue. Install the package, create an API key in the console available to you and pass it to the application via an environment variable TYPESAFE_API_KEY —do not insert the secret itself into the source code or browser.
uv add typesafe-sdk
export TYPESAFE_API_KEY="ваш_ключ"
from typesafe_sdk import Choice, TypeSafeClient
ticket = {
"message": "После обновления не открывается страница оплаты."
}
with TypeSafeClient() as client:
result = client.system_one(
state=ticket,
questions={
"team": Choice(
instructions="К какой команде направить обращение?",
criteria={
"billing": "Вопросы о списании или сумме платежа",
"technical": "Ошибка сайта или невозможность выполнить действие",
"other": "Недостаточно данных или другая тема",
},
),
},
)
print(result.choices["team"].choice)In the example, the question is deliberately narrow: choose, who should review the application, rather than determining the exact cause of the failure and not correcting the payment. First, print out the result and compare it with how a person marks the same request. Do not add automatic payments, refunds, or account changes after this.
TypeSafe also has an HTTP API POST https://api.typesafe.ai/v1/systemone, and AI Gateway and some integrations use their own formats and field names. Check the API with official OpenAPI description, and the Python example is with official SDK repository. Always make the API call on the server; The key cannot be placed in client JavaScript.
How to test Jev on your task
The most useful first experiment is not to ask the model to write a demo for a presentation, but to take a small real process with known correct answers.
1. Formulate one solution. For example: select a support team from three options. Do not mix classification, damage assessment and recommendations on what to answer the client in one question.
2. Describe the boundaries of the categories. Fix when a request relates to billing, when to technical support, and what to do if there is insufficient data. Ask two people to independently label the sample: if they are systematically arguing, the task is not yet clearly formulated.
3. Collect examples with known markup. Start with at least a hundred anonymized cases, if such a volume is available. Remove names, phone numbers, addresses and payment information. Include regular, borderline, and partial messages. Leave some of the examples separately for the final check - do not adjust the criteria for all and do not evaluate using the same examples.
4. Compare with the current method. Run the existing rules, the current model and Jev on the same cases. Calculate the accuracy for each category, the proportion of cases sent for manual review, the time and cost of the entire process. Average accuracy can hide critical mistakes: look separately at those classes of errors whose cost is high.
5. Examine the probabilities and thresholds in your sample. High probability - a signal for verification, not a magical certificate. See how often answers with a conditional probability of 0.8 are actually correct in your stream; compare the thresholds and count how many erroneous automatic decisions they allow. Separate the probability of a specific option from the general confidence assessment and from Score.
6. Launch shadow mode. In the real stream, Jev is currently only recording his sentences without changing anything. The operator continues to work as before. After some time, analyze the discrepancies and check whether new messages differ from the test sample.
7. Incorporate actions gradually. Start with a reversible action - for example, offering a turn to an employee. For blocks, returns, write-offs and external shipments, leave independent checks in the code and human confirmation. Don't let Jev's prediction expand permissions on its own.
For a Russian-language product, include Russian, spoken and mixed messages in the test set. Don't infer quality in Russian from the English demo or the fact that the API accepted Russian text. Check your wording, jargon, errors and common omissions.
Where is the boundary of possibilities?
- Jev does not write coherent answers. If a solution needs to be explained to the client, a separate generative model or person does this.
- Jev does not perform application actions. To send a letter, grant access or call a tool, your code, server rights and verifications are needed.
- Limited format does not mean error-free meaning. The model may choose one of the allowed items, but misunderstand the situation.
- Don't expect to work with media data directly. Documented integrations describe a text state. For image, audio or video, first extract the text with a suitable tool and check the quality of this step separately.
- Do not submit real personal or sensitive data to the trial API without checking the conditions. Check storage, processing, disposal policies and available contractual guarantees with the vendor and your gateway; until then, use synthetic or anonymized examples.
- Check the independence of questions. If the answer to the second question depends on the solution to the first, divide it into two application steps. A couple of questions in one call is not a chain of reasoning.
So is it worth trying?
If your program says "read this and choose one of these options", Jev looks like a clear candidate for a pilot. Start by routing requests, classifying documents, or checking an agent's result - with impersonal examples and without automatic consequences at first.
If the task sounds like “explain, invent, write an answer or find an unknown option,” leave it to the chat model. In many products, these components will work together: the generative model conducts the dialogue and suggests action, Jev evaluates the limited question, and regular code applies rules and checks permissions.
The new idea here is not that the AI suddenly stopped making mistakes. The idea is a more convenient contract between the model and the program: the question and answer type are specified explicitly, uncertainty can be seen, and the action remains under the control of the code. How reliable and profitable it is - only testing it on your task will decide.
Sources and materials for continuation:
- Jev and System One announcement from TypeSafe AI
- Official documentation TypeSafe · OpenAPI · Python SDK
- How to integrate Jev: AI SDK, TanStack, Cloudflare, LangChain and other ways - Vercel
- What is Jev and where is it appropriate - Vercel
- Thresholds, probability and confidence - Vercel
- Jev at LangSmith Evals – LangChain
Access, pricing, model names and SDKs are changing quickly. Information in this article was verified on September 23, 2026; For current conditions, see the documentation and account of the selected provider.